Lakshmanan LN
AI/ML Engineer — GenAI & RAG systems, MLOps, ML architecture
I write long-form, first-principles posts on the systems layer underneath modern ML: attention internals, inference engines, and the training dynamics behind why models behave the way they do.
Latest Posts
Speculative Decoding: How Guessing Tokens You Then Throw Away Speeds Up LLM Inference
Here’s a claim that sounds like it can’t possibly be true: you can use a small, weak model to guess several of a large …
Read More
Agent Harnesses: Why the Same Model Scores 34 Points Apart on the Same Benchmark
Take Claude Sonnet 4.5 — same weights, same API, same day — and run it on SWE-bench Verified under two different scaffolds. Under a …
Read More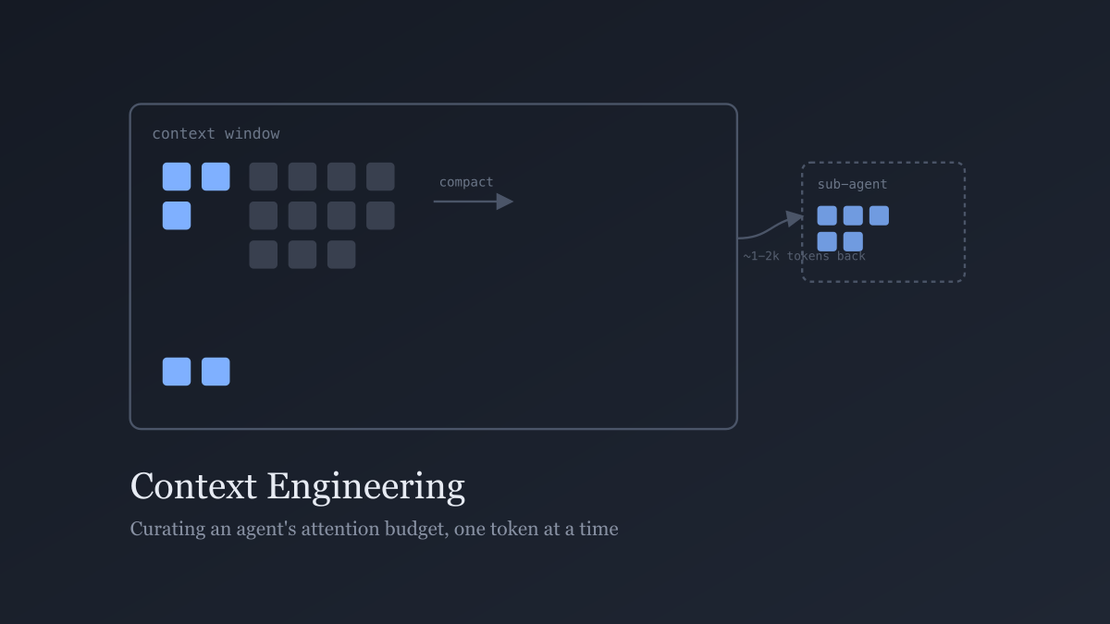
Context Engineering: Why Contexts Fail, and the Four Moves That Fix Them
In June 2025, Andrej Karpathy posted a one-line reframe that stuck: “+1 for ‘context engineering’ over ‘prompt …
Read MoreFind Me Elsewhere
Shorter takes on X, video walkthroughs on YouTube.

@geekylax on X
Shorter and faster than the blog — half-formed ideas, quick reactions to papers, and whatever I'm currently stuck on.
Latest post Speculative Decoding: How Guessing Tokens You Then Throw Away Speeds Up LLM Inference Share it on X Follow on X