AI Agents
- Home /
- Categories /
- AI Agents
Agent Harnesses: Why the Same Model Scores 34 Points Apart on the Same Benchmark
Take Claude Sonnet 4.5 — same weights, same API, same day — and run it on SWE-bench Verified under two different scaffolds. Under a …
Read More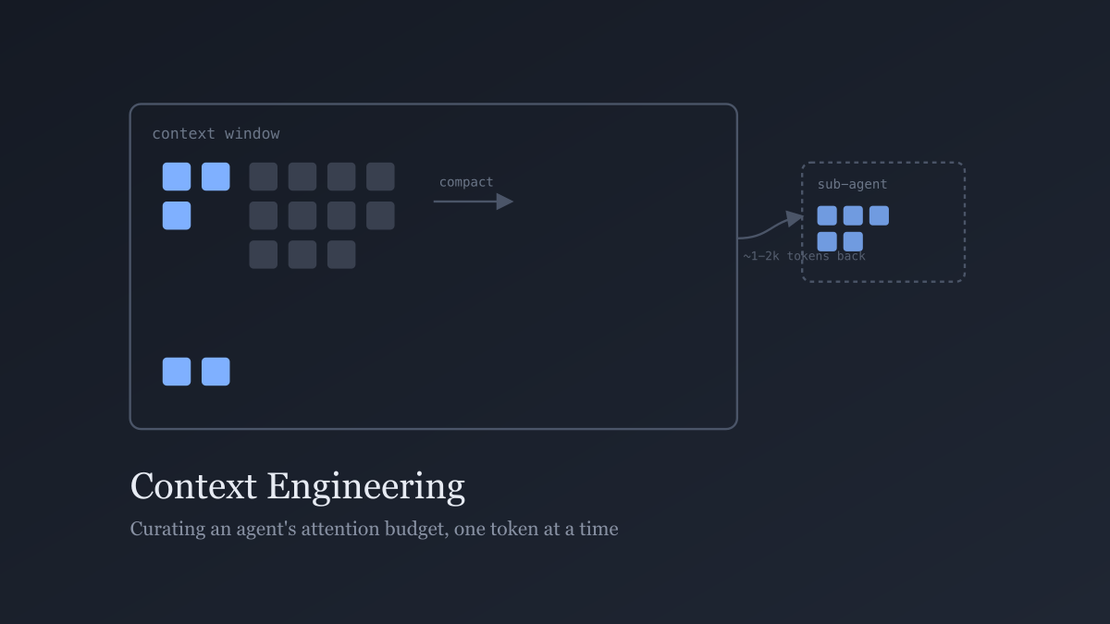
Context Engineering: Why Contexts Fail, and the Four Moves That Fix Them
In June 2025, Andrej Karpathy posted a one-line reframe that stuck: “+1 for ‘context engineering’ over ‘prompt …
Read More